Here's one small function, run on Node 26 with the same input every time:
function dist(p) {
  return Math.sqrt(p.x * p.x + p.y * p.y);
}
Then the same function again, but with V8 stopped at a different stage each time:
Ignition only:   50.9 ns per call
+ Sparkplug:     31.9 ns
+ Maglev:         1.65 ns
+ TurboFan:       1.19 ns   ← 43× faster than the first line
The code never changed. The only thing that changed is how hard V8 worked on translating it.
The mental model: a translator who works harder on popular pages#
Picture a translator handed a book in a language your computer doesn't speak.
- For a page read once, they translate it out loud on the spot, line by line.
- For a page read a few times, they write down a quick word-for-word draft.
- For a page read hundreds of times, they write a proper translation.
- For the page everyone reads all day, they polish it, assuming the page always looks the way it has so far.
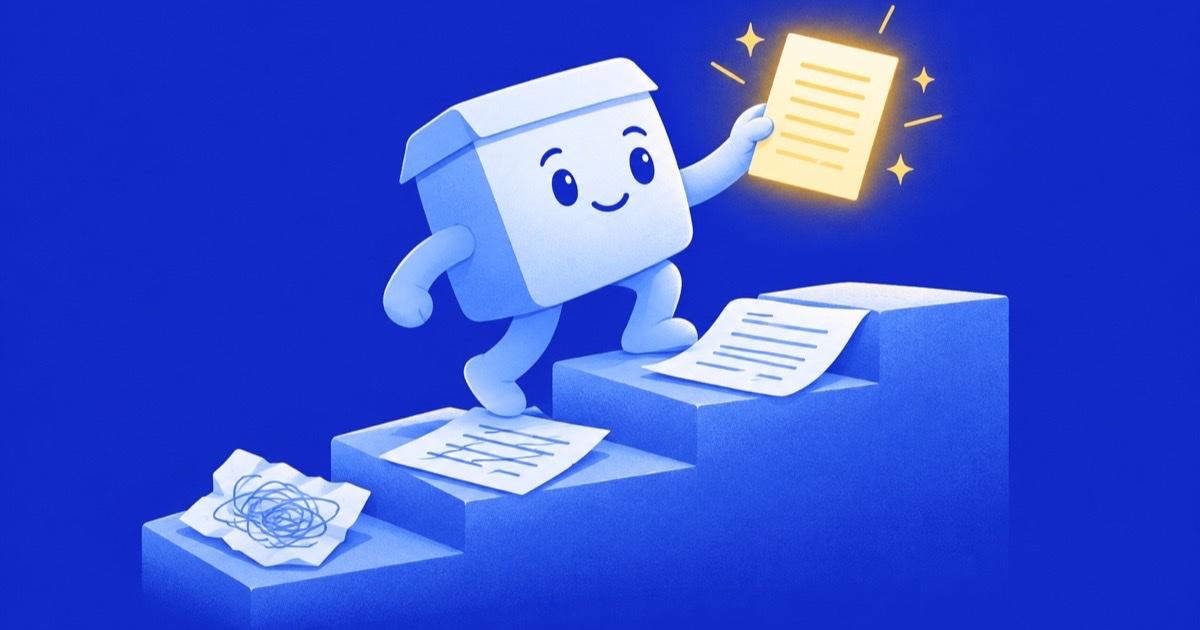
V8 translates your JavaScript in stages, and only spends extra effort on code that runs a lot.
Each stage is called a tier, and the whole approach is JIT (just-in-time) compilation: the machine code is made while the program runs, not before.
 Interpreting on the spot is quick to start but slow per line, like Ignition. Photo: Blossom Ozurumba, CC BY-SA 4.0, via Wikimedia Commons
How it works#
V8 has four tiers. Each one makes faster code, but takes longer to make it:
| Tier | Translator analogy | What it does |
|---|---|---|
| Ignition | reading out loud | Interprets bytecode, a compact list of simple instructions made from your source |
| Sparkplug | word-for-word draft | Turns bytecode straight into machine code, with almost no thinking |
| Maglev | proper translation | A fast optimizing compiler that uses the types it has seen so far |
| TurboFan | polished translation | The slow, heavy optimizer for the hottest code |
Every function starts in Ignition. While it runs, V8 counts how often it's called and records what it sees: "p always has x and y, and they're always numbers." That record is called type feedback.
When a function gets hot (runs a lot), V8 moves it up a tier. For dist above, V8's own trace showed:
- Maglev after about 500 calls, taking 0.08 ms to compile.
- TurboFan after about 16,900 calls, taking 0.61 ms to compile. That's about 8× more compile time for code about 1.4× faster.
That trade is why the tiers exist. Most code runs once, at startup. Spending TurboFan's effort on all of it would make every page load slower and save nothing.
A function's life in V8
- 1
Your source
Parsed into bytecode
- 2
Ignition
Every function starts here, counting calls and recording types
- 3
Sparkplug
Quick machine code for warm functions
- 4
Maglev
Optimized with the types seen so far
- 5
TurboFan
Heaviest optimization for the hottest code
- Fast code keeps running
- Optimized code thrown away
- Back to the lower tiers
The catch: optimized code is a bet#
Maglev and TurboFan are fast because they assume the future looks like the past. "Every p.x has been a number, so skip the type check and do raw number math."
If that assumption breaks, the fast code is wrong. So V8 throws it away and goes back to a lower tier. This is called deoptimization. Here, a single call with a string inside was enough:
dist({ x: "3", y: 4 }); // V8 drops both Maglev and TurboFan code for dist
The function still works, it just runs slower until V8 learns the new types and optimizes again.
In practice#
You can't pick a tier, and you don't need to. V8 decides. But two habits follow from the model:
1. Keep hot code predictable. Pass the same kinds of values to a hot function: same object shapes, numbers staying numbers. That keeps the bet safe. (For why object shape matters, see hidden classes.)
// before: one function, many types: harder to optimize
format(42); format("42"); format(null);

// after: one type per hot function
formatNumber(42);
2. Warm up before you measure. The first few hundred calls of any benchmark measure Ignition, not your code at its best. Run the code many times, then time it. Every number in this post was taken after a warm-up.
Honest stakes: for most app code (click handlers, a React render, a fetch), the tiers just work and none of this is worth thinking about. It matters in hot loops: parsers, data processing, animation, game logic. Even there, profile first. A function that never gets hot never reaches TurboFan anyway.
Say it in an interview#
"V8 is a JIT engine with tiers. Everything starts in Ignition, an interpreter that runs bytecode and records type feedback. Code that runs often gets compiled by Sparkplug, then optimized by Maglev and finally TurboFan, which make fast machine code based on the types seen so far. If those types change, V8 deoptimizes and falls back to a lower tier. So JavaScript is both interpreted and compiled, and keeping hot code type-stable lets it stay in the fast tiers."
Cheat sheet#
| Remember | Detail |
|---|---|
| Ignition | Interpreter. Every function starts here |
| Sparkplug | Quick, non-optimizing machine code |
| Maglev | Fast optimizer, uses type feedback |
| TurboFan | Slow, strongest optimizer, for the hottest code |
| Deoptimization | Types change → optimized code thrown away |
| Measured here | Same function: 50.9 ns → 1.19 ns per call (43×) |
TL;DR#
- V8 translates JavaScript in four tiers, spending more effort only on hot code.
- Optimized code is a bet that types stay the same. A surprise type cancels it.
- The same function ran 43× faster in TurboFan than in Ignition alone.
- Keep hot functions type-stable, warm up before benchmarking, and profile before optimizing.
Advanced · optional
Going deeper#
Everything above is enough to explain this in an interview. This part is for the curious: full numbers, edge cases and what's still unproven.
How the numbers were measured#
Node 26.13 (V8 14.6), Apple M3 Pro, median of 7 fresh processes per setting.
The benchmark calls dist through a total function that sums it over 10,000 points like { x: i % 97, y: i % 13 }. After 300 warm-up runs, it times 2,000 more and divides by the number of points. V8's --max-opt flag caps the highest tier allowed:
| Flag | Highest tier | ns per point |
|---|---|---|
--max-opt=0 | Ignition | 50.9 |
--max-opt=1 | Sparkplug | 31.9 |
--max-opt=2 | Maglev | 1.65 |
--max-opt=3 | TurboFan | 1.19 |
The jump from Sparkplug to Maglev is the big one, because that's where V8 starts using type feedback: once it knows p.x is always a number on the same object shape, the property read becomes a single memory load and the math becomes raw float operations. TurboFan's extra win here comes mostly from heavier work like inlining and better register use.
In this test, dist gets inlined into total, so the timings describe the hot loop as a whole. A bigger function would show a different ratio.
How the tier-ups were traced#
node --trace-opt --trace-deopt --no-concurrent-recompilation trace.js
The script called dist 20,000 times, printing a marker every 25 calls, then passed it one object with a string. The trace printed marking dist for optimization to MAGLEV, reason: hot and stable near call 500 and the same for TURBOFAN_JS near call 16,900. After the string input it printed marking dependent code ... for deoptimization, reason: dependent field representation changed for both the TurboFan and Maglev code.
--no-concurrent-recompilation makes compiling happen right away on the main thread, so the call count is easy to read. Normally V8 compiles Maglev and TurboFan code on background threads and swaps it in when ready.
The thresholds aren't fixed call counts#
V8 doesn't tier up after a set number of calls. Each function has an interrupt budget that runs down as its bytecode executes, scaled by the function's size, and loops count too. So a tiny function and a big one reach Maglev after very different call counts. Treat "500" and "16,900" as what happened for this one function, not as rules.
The trace doesn't show Sparkplug, because Sparkplug isn't counted as optimization. It kicks in early, before Maglev.
On-stack replacement (OSR)#
A function called once that runs a long loop never gets "called a lot". V8 handles that with on-stack replacement: it compiles optimized code for the loop and jumps into it in the middle of the running call. That's why a single long loop at the top of a script still gets fast.
Tiers have changed over time#
Older articles describe only two tiers: the Ignition interpreter and the TurboFan optimizer. Sparkplug shipped in 2021 (Chrome 91) and Maglev in 2023 (Chrome 117) to fill the gap between "slow interpreter" and "expensive optimizer". Newer V8 versions are also building Turboshaft, a new backend for TurboFan, and Turbolev, which feeds Maglev's front end into it. The model in this post (cheap tiers first, expensive tiers for hot code, deopt on surprise) has stayed the same.
Further reading#
- Ignition and TurboFan, V8 blog
- Sparkplug, a non-optimizing JavaScript compiler, V8 blog
- Maglev, V8's fastest optimizing JIT, V8 blog
Start the discussion
Questions, corrections, a better approach? I read and reply to every comment.